For teams going agentic

AI FORGING

The counterpoint to vibe coding.

What if your codebase is getting worse with every feature you ship? Going agentic is easy — going agentic without wrecking quality is the hard part. AI Forging is the discipline for handing AI whole units of work while quality and velocity compound instead of collapse.

The landscape

Four ways to build with AI.

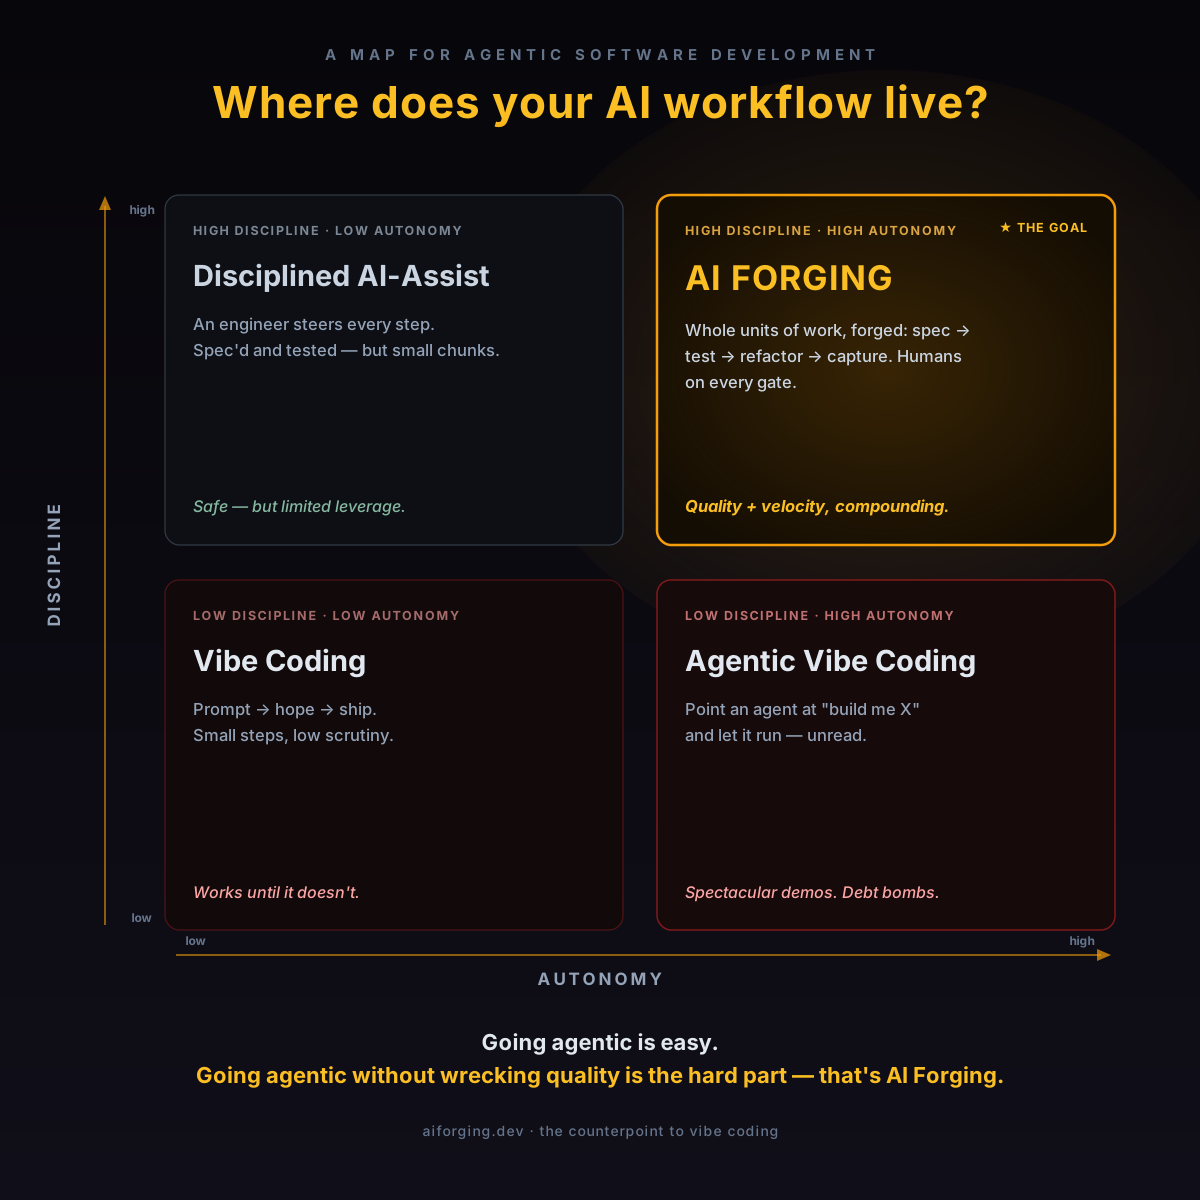
Autonomy and discipline are two different axes. "Agentic" means you hand the AI a whole unit of work. "Vibe" means little discipline wraps it. Cross them and you get four very different places to live — including the trap almost nobody names: agentic vibe coding.

A map for agentic software development: autonomy versus discipline. Vibe Coding (low autonomy, low discipline), Disciplined AI-Assist (high discipline, low autonomy), Agentic Vibe Coding (low discipline, high autonomy), and AI Forging (high discipline, high autonomy — the goal).

Click the map to open it full-size ↗

The idea

AI Forging is layered.

It isn't a single tool. It's a philosophy, a methodology that serves it, and a concrete implementation of that methodology — three layers with very different lifecycles.

1
The Why — Philosophy

The problems worth solving

What goes wrong when we build with agentic AI, and why quality has to compound instead of decay. Tool-agnostic and the part that endures longest.

2
The How — Methodology

One way to solve them

Spec → plan → test-first execution → refactoring in isolated sub-agents → knowledge captured so it scales. Framed as one approach, not the only one — others are welcome.

3
The Implementation — Open Source

A tool that runs the method

The open-source Claude Code plugin — with strong, opinionated bets on architecture. One implementation of the methodology. You could disagree with every opinion and still hold the philosophy.

Layer 1 — The Why

Speed got cheap. Quality didn't.

AI makes producing code nearly free. Without structure, every feature shipped makes the codebase worse — and eventually the AI itself starts hallucinating against the mess it helped create. This is the problem worth solving, and it outlives any single tool.

Quality drift compounds

AI output silently diverges from your conventions. Small drift today becomes structural debt in six months — hidden behind a green CI badge.

Velocity masks debt

Features ship fast while the codebase rots underneath. The rework cycle begins invisibly, then velocity collapses.

Knowledge evaporates

Hard-won decisions live in chat transcripts and individuals' heads. Nothing is codified. Turnover resets the clock.

No audit trail

No record of what was built, why, or by whose approval. Governance and regulatory blind spots.

Layer 2 — The Method

Fire. Hammer. Tempering.

A metallurgy metaphor: raw material becomes stronger through structured transformation — not by hoping for the best. Each pass through the forge leaves the codebase stronger than it started.

Fire

Test before you code

AI-powered TDD. Tests capture intent before a line of implementation exists — the double-entry accounting of software.

Intent, verified — not eyeballed.

Hammer

Refactor against patterns

After the tests pass, one fresh-context sub-agent per pattern reworks just the changed code — in parallel, no drift, no fatigue.

Consistency without human fatigue.

Tempering

Capture knowledge that scales

One correction, one pattern file. Adding the 50th costs no more than the 5th. No monolith, no context ceiling.

The system gets smarter, not heavier.

Then you check it.Optional

The forge builds the feature. Two further stages check it — one reads the running product, one reads the diff. Both are optional, and neither writes a feature.

Browser testing

Walk the product, fix nothing

Every feature with a screen carries a QA checklist. The AI walks it in a real browser, marks the items only a person can judge so you work those in parallel, and records one line of evidence per step.

It never fixes what it finds. A failing step means the product and the spec disagree — it says nothing about which one is wrong, and an auto-fixer would cement the wrong answer and hand you a green checklist saying so.

Findings become conversations, not commits.

Review loop

Review, triage, fix, repeat

Rounds of code review across every repo the feature touched — but every finding is verified against the source before it's accepted. About a third of review findings describe behavior that was deliberate.

It stops on a real condition, not a finding count: counts settle into a noisy floor and severity can rise after falling for five rounds. Both were tried. Both misled.

Rounds that converge instead of circling.

And then it stops and hands you the full test suite. Every automated run — Fire, Hammer, every fix agent — is scoped to the one suite that feature owns, because a three-second loop and a three-minute loop are not the same activity at different speeds. That trades a real risk: a regression in a different feature won't show up. So no stage here ever runs the whole suite, and every one of them ends by telling you, in words, that it's your turn.

For Teams

One engineer forges. Anyone can pick it up.

Every feature's spec, plan, QA checklist and review record lives in a forge workspace — a git repository your whole team clones. That single decision is what turns a personal AI workflow into a team one.

Next week

Someone goes on vacation mid-feature

They're three work items in and gone for a week. A teammate opens the same feature folder and gets what's done, what's next, what was deliberately deferred, and every finding still open.

No handover meeting. No archaeology.

Three months later

You need to extend what your AI built in March

Point it at the feature folder. It reads the specs — the business intent and the engineering intent, written down at the time by the people who decided them.

It doesn't have to guess. That distinction gets bigger every month.

Every pull request

One review, and everyone's next feature is better

Your sharpest reviewer catches the AI doing something less than ideal and captures it as a pattern file — one correction, one file.

Every engineer's next feature is checked against it. Expertise stops being trapped in the pull request where it happened.

The alternative is asking your AI to reverse-engineer your own intent.

"The code for this lives roughly in these folders. It currently does A, B and C. Now I'd like it to do X."

That's the usual way to reopen an old feature, and it asks the AI to reconstruct why from what. It's tedious, it's error-prone, and the blind spots it produces are large and quiet — you don't find out what it misunderstood until the change ships.

A feature folder hands it the reasoning directly. That's the difference between an AI that understands your feature and one that has inferred a plausible story about it.

Three commands carry it: one to start a feature, one to pick up any feature — yours or a teammate's — and one that wires a freshly cloned workspace to a new engineer's machine.

/aiforging:forgestart something new /aiforging:resumepick up anything /aiforging:joinonboard a teammate
Governance

AI Forges. Humans decide.

Nothing autonomous, nothing silent. Every proposal passes a human gate before it merges — reviewed at feature completion, not one step at a time.

1Review the tests — do they capture your intent?
2Code review at the PR
3Architecture decisions
4Deployment authorization
The Movement

One philosophy. Many ways to live it.

The most important layer is the Why, and it belongs to everyone. The methodology below it is one route through the problem — yours might be better. The plugin is one implementation — there could be others, for other tools, stacks, and architectures. Take the ideas, build your own, and share what you learn.

Vibe Coding

  • Prompt → hope → ship
  • Quality is a snapshot
  • Knowledge lives in the chat history
  • Best practices are whatever the AI recalls
  • Works until it doesn't

AI Forging

  • Specify → prove → capture
  • Quality compounds every cycle
  • Knowledge lives in reusable files
  • Best practices enforced automatically
  • Each piece makes the next one better
Layer 3 — The Implementation
Open source · Claude Code plugin · v0.4.0

Install the reference implementation.

A Claude Code plugin that runs the whole method — spec, TDD, pattern-driven refactoring, knowledge capture, and the two optional verification stages — with opinionated, domain-driven architecture on top. Built for established codebases that already feel the AI-generated sprawl. Prescriptive on purpose.

# Install superpowers (the TDD + sub-agent foundation)
/plugin marketplace add obra/superpowers
/plugin install superpowers@superpowers-dev

# Install AI Forging
/plugin marketplace add aiforging/aiforging
/plugin install aiforging@aiforging

# Then bootstrap a workspace
/aiforging:setup

# Start a feature
/aiforging:forge my-feature "what I want to build"

# Optional, once it's built
/aiforging:browser-testing
/aiforging:review-loop

Symfony / PHP / Doctrine is the happy path today; other stacks work to the degree the conventions apply. Try it on something real and open an issue about what broke.

FAQ

Hard questions. Honest answers.

Every new idea meets skepticism. Here are the objections we hear most — and the answers, backed by a working system.

Can I use it today?
Yes. AI Forging ships as an open-source Claude Code plugin — install it and run /aiforging:setup to bootstrap a workspace. It's at v0.4.0, MIT licensed, and running against real production codebases — and the principles apply even if you never install a thing.
Does this work for a team, or is it really a one-person thing?
It's built for teams, and that's the part most AI workflows skip. The forge workspace is a git repository your whole team clones — every feature's spec, plan, QA checklist and review record lives in it. One engineer starts a feature; anyone can pick it up with /aiforging:resume. When a reviewer catches the AI doing something less than ideal, they capture it as a pattern file and every engineer's next feature is checked against it. It works solo too, and most of the benefit still lands — three months from now you're effectively a different engineer looking at your own feature, with no more memory of the decisions than a colleague would have. Sharing it is what adds the handoff on top.
What's the deal with workspaces?
A forge workspace is where the forging artifacts live — every feature's spec, plan, QA checklist and review record, plus the pattern library — in one place instead of scattered through your codebases. Your code repos stay code repos.

It's a git repository of its own, which is what makes it shareable: your team clones it like anything else. Roughly one workspace per project.

That pays off most when a project spans several repos. A single workspace can reference a backend, a frontend and whatever else — and a feature that touches one of them, or all of them, still gets one spec and one plan instead of three that drift apart.

And if your project is just one repo? Don't create a second one — the workspace installs inside it. Same workflow, one less thing to clone.
Does every engineer have to be full-stack for this to work?
In practice, one engineer owning a feature end to end — front-end and back-end — works better than splitting it between two specialists, and the framework is shaped for that. The AI writes the code; the guardrails are what make it reasonable for one person to review across the whole stack, and it removes the coordination cost that used to justify the split. Depth still matters: your strongest reviewer in an area reviews those pull requests more closely — and captures what they catch, so their expertise reaches everyone's next feature instead of staying in that one review.
Isn't this just TDD with a brand on it?
TDD is one of three stages — the Fire. Alone, it proves today's code works; it doesn't capture patterns, automate refactoring against them, or compound quality across sessions. Fire → Hammer → Tempering is a flywheel where each pass makes the next one better.
Why write the test first — can't the AI just add tests afterward?
Because order changes what the test measures. Write the test first, and its job is to answer "does this match the intended outcome?" — the code then has to earn a passing test. Write it after, and its job quietly shrinks to "does this match the code I already wrote?" — now it just certifies whatever the AI produced, intent or not. Test-after locks in behavior; test-first locks in intent — the difference between a test that catches a wrong feature and one that rubber-stamps it.
I already add lessons to a big CLAUDE.md. Same thing?
A single instruction file hits a ceiling — context fills up, signal drowns in noise, and the AI starts ignoring half your rules. AI Forging uses one file per pattern, each reviewed by a fresh-context agent. The 50th pattern costs no more than the 5th. A list versus an architecture.
Isn't this just good engineering with a fancy name?
Good principles, yes — but the AI-orchestration layer is new: bounded-context sub-agents, automated pattern enforcement, post-TDD loops that check every changed file against every known pattern. Good engineering is a value; AI Forging is a system, and a system needs a name to spread.
Vibe coding works fine for my projects.
For prototypes and throwaway scripts, it does — that's not the problem this solves. For production systems that outlive team changes and compound over years, vibe coding has no answer. This is what comes after it, when the code has to last.
Aren't you just coining a term to get famous?
The system exists and runs across several production codebases today — patterns, anti-patterns, test suites, sub-agent orchestration, real working code. It draws on 30 years of engineering and daily AI-assisted development since 2023. The name just lets it be taught, shared, and improved.
Won't this be obsolete in six months as AI improves?
More powerful AI without guardrails just means bad code faster. Structure matters more as models improve, not less. The forge cycle is model-agnostic — as the AI gets better, the Fire burns hotter and the patterns get richer. It rides the models; it doesn't compete with them.
This is too heavyweight. I just need to ship.
The old knock on rigor was "it's too slow." AI changed that: the AI runs the test-first cycles, the refactoring, and the pattern review. You define intent. Doing more means doing better — not doing slower.
Where's the proof? Show me metrics.
The proof is structural. Several production codebases — frontend, backend, and more — orchestrated through one framework, with growing pattern libraries, independent test suites, and anti-pattern files that stop the same mistake twice. It's a working system, not a whitepaper.